Cloudron makes it easy to run web apps like WordPress, Nextcloud, GitLab on your server. Find out more or install now.


Skip to content
  • Categories
  • Recent
  • Tags
  • Popular
  • Bookmarks
  • Search
Skins
  • Light
  • Brite
  • Cerulean
  • Cosmo
  • Flatly
  • Journal
  • Litera
  • Lumen
  • Lux
  • Materia
  • Minty
  • Morph
  • Pulse
  • Sandstone
  • Simplex
  • Sketchy
  • Spacelab
  • United
  • Yeti
  • Zephyr
  • Dark
  • Cyborg
  • Darkly
  • Quartz
  • Slate
  • Solar
  • Superhero
  • Vapor

  • Default (No Skin)
  • No Skin
Collapse
Brand Logo

Cloudron Forum

Offical apps | Community apps | Demo | Docs | Install
timweddeT

timwedde

@timwedde
Unfollow Follow
Scheduled critical security release for PHP
More details here: PHP scheduled critical security release CVE-2026-115560
About
Posts
5
Topics
3
Shares
0
Groups
0
Followers
0
Following
0

Posts

Recent Best Controversial

  • Help with improving GitLab startup latency
    timweddeT timwedde
    GitLab

    I noticed that over time my GitLab instance startup times became slower and slower, but not always consistently. I eventually managed to track this down to a recursive directory ownership command that the startup script runs unconditionally:
    chown -R git:git /app/data /run/gitlab /tmp/gitlab

    My instance has about 350k files and directories in its artifact storage, which causes this command to take upwards of 3 minutes when filesystem caches are cold. Needless to say this is quite annoying when updating or restarting the app after some time, when the FS caches are cold. It only takes ~30s when the caches are hot, but this is rarely the case for updates for daily/weekly restarts. As such, I regularly lose 3-5 minutes on restarts and updates, which adds up over time.
    This problem also gets worse as the instance grows, the more files and directories there are, the longer this command will take to run.

    Is it required to run this command on every startup? If not, could it be made into a one-time thing or somehow be made conditional to only run when actually required? This would greatly reduce startup times (and thus downtime during updates) for me and presumably everyone else with larger instances.


  • Sidekiq Loop takes down GitLab instance
    timweddeT timwedde
    GitLab

    I did read through those pages, and that is in fact how I arrived at the queue state representation that I posted above. Unfortunately clearing the queue did not help for long: The tasks kept reappearing.

    I have, however -through many trials and tribulations- possibly managed to resolve this problem over the weekend: Logging into the GitLab postgres DB, I found a table called container_repositories which contained references to the repos that were used to test the registry feature. After truncating that table, clearing the queued jobs and restarting GitLab (as well as the entire instance for good measure), it seems to have slowly reverted back to normal over the past 24 hours, at least for the time being. I'm gonna keep an eye on it some more, but it's looking like that might've been it.

    It's a bit weird that GitLab would keep spinning tasks endlessly like this, but then again it's a massive piece of software, so perhaps this is simply a strange bug in GitLab itself. In any case, the container registry instructions for GitLab integration did not seem to work that well for us as they produce this behavior whenever I try them out (I tried it twice to make sure), so maybe another look at those could be warranted.


  • Sidekiq Loop takes down GitLab instance
    timweddeT timwedde
    GitLab

    After trying out the Container Registry integration (but eventually deciding that it's not that useful to us), it seems to be the case that something within the process outlined in the docs has left our GitLab instance in an invalid state, which breaks it to the point of becoming unusable.

    The problem is that, apparently, a Sidekiq job is stuck in an infinite loop: It keeps spawning. As soon as capacity is available on a Sidekiq worker, a new job pops up. The specific job is called ContainerRegistry::DeleteContainerRepositoryWorker, I have reproduced one of its queue representations below:

    {"retry"=>0, "queue"=>"default", "version"=>0, "status_expiration"=>1800, "queue_namespace"=>"container_repository_delete", "args"=>[], "class"=>"ContainerRegistry::DeleteContainerRepositoryWorker", "jid"=>"8e56ce71ec9cf7c4a0eae8fd", "created_at"=>1708097426.835311, "meta.caller_id"=>"ContainerRegistry::DeleteContainerRepositoryWorker", "correlation_id"=>"caa24956212e875d03537fd71282cba2", "meta.root_caller_id"=>"Cronjob", "meta.feature_category"=>"container_registry", "meta.client_id"=>"ip/", "worker_data_consistency"=>"always", "size_limiter"=>"validated", "enqueued_at"=>1708097426.838449}
    

    This effectively suffocates the queue, no other task can be processed and the entire instance grinds to a halt. The web interface works, but most features simply hang because their background jobs never get the chance to run.

    Here is a very small excerpt from the instance logs:

    Feb 16 16:34:20{"severity":"INFO","time":"2024-02-16T15:34:20.544Z","retry":0,"queue":"default","version":0,"status_expiration":1800,"queue_namespace":"container_repository_delete","args":[],"class":"ContainerRegistry::DeleteContainerRepositoryWorker","jid":"1b599d25b46a565485c3f4f6","created_at":"2024-02-16T15:34:20.409Z","meta.caller_id":"ContainerRegistry::DeleteContainerRepositoryWorker","correlation_id":"caa24956212e875d03537fd71282cba2","meta.root_caller_id":"Cronjob","meta.feature_category":"container_registry","meta.client_id":"ip/","worker_data_consistency":"always","size_limiter":"validated","enqueued_at":"2024-02-16T15:34:20.413Z","job_size_bytes":2,"pid":69152,"message":"ContainerRegistry::DeleteContainerRepositoryWorker JID-1b599d25b46a565485c3f4f6: done: 0.120002 sec","job_status":"done","scheduling_latency_s":0.011408,"redis_calls":8,"redis_duration_s":0.007204,"redis_read_bytes":9,"redis_write_bytes":1246,"redis_queues_calls":4,"redis_queues_duration_s":0.002866,"redis_queues_read_bytes":5,"redis_queues_write_bytes":707,"redis_shared_state_calls":4,"redis_shared_state_duration_s":0.004338,"redis_shared_state_read_bytes":4,"redis_shared_state_write_bytes":539,"db_count":10,"db_write_count":3,"db_cached_count":1,"db_replica_count":0,"db_primary_count":10,"db_main_count":10,"db_ci_count":0,"db_main_replica_count":0,"db_ci_replica_count":0,"db_replica_cached_count":0,"db_primary_cached_count":1,"db_main_cached_count":1,"db_ci_cached_count":0,"db_main_replica_cached_count":0,"db_ci_replica_cached_count":0,"db_replica_wal_count":0,"db_primary_wal_count":0,"db_main_wal_count":0,"db_ci_wal_count":0,"db_main_replica_wal_count":0,"db_ci_replica_wal_count":0,"db_replica_wal_cached_count":0,"db_primary_wal_cached_count":0,"db_main_wal_cached_count":0,"db_ci_wal_cached_count":0,"db_main_replica_wal_cached_count":0,"db_ci_replica_wal_cached_count":0,"db_replica_duration_s":0.0,"db_primary_duration_s":0.033,"db_main_duration_s":0.033,"db_ci_duration_s":0.0,"db_main_replica_duration_s":0.0,"db_ci_replica_duration_s":0.0,"cpu_s":0.061245,"worker_id":"sidekiq","rate_limiting_gates":[],"duration_s":0.120002,"completed_at":"2024-02-16T15:34:20.544Z","load_balancing_strategy":"primary","db_duration_s":0.038678,"urgency":"low","target_duration_s":300,"target_scheduling_latency_s":60}
    Feb 16 16:34:20{"severity":"INFO","time":"2024-02-16T15:34:20.553Z","retry":0,"queue":"default","version":0,"status_expiration":1800,"queue_namespace":"container_repository_delete","args":[],"class":"ContainerRegistry::DeleteContainerRepositoryWorker","jid":"6be37d4007f559ced52a8eb5","created_at":"2024-02-16T15:34:20.535Z","meta.caller_id":"ContainerRegistry::DeleteContainerRepositoryWorker","correlation_id":"caa24956212e875d03537fd71282cba2","meta.root_caller_id":"Cronjob","meta.feature_category":"container_registry","meta.client_id":"ip/","worker_data_consistency":"always","size_limiter":"validated","enqueued_at":"2024-02-16T15:34:20.538Z","job_size_bytes":2,"pid":69152,"message":"ContainerRegistry::DeleteContainerRepositoryWorker JID-6be37d4007f559ced52a8eb5: start","job_status":"start","scheduling_latency_s":0.015051}
    

    It's just this, over and over again, multiple times a second. I've tried canceling the tasks manually via the Rails console, but they just keep spawning.
    Has anybody encountered this behavior before? Is there a way to prevent these tasks from spawning?

    The especially weird thing is that this only started happening after trying out the Container Registry integration, but also not immediately. Even disabling the registry again does nothing to quell the issue, which is particularly frustrating: Currently I have no way back to a stable state (that I can see, at least).

    Here's a screenshot of when things went south, the spike in jobs is incredibly drastic:
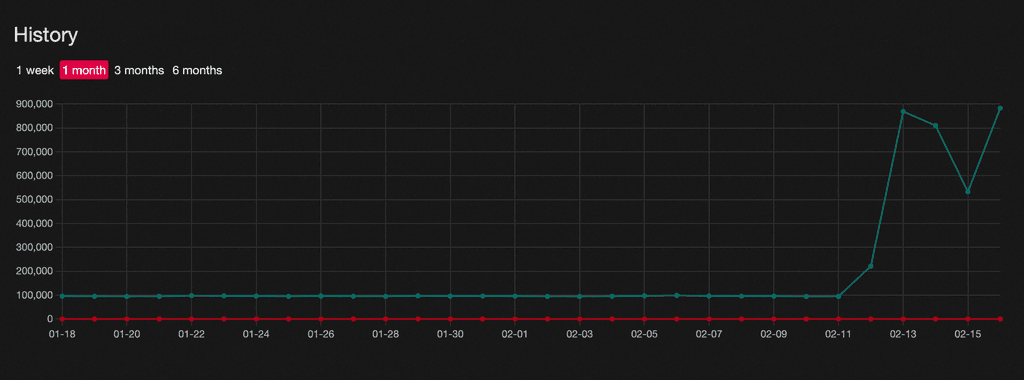
    Screenshot 2024-02-16 at 16.41.08.png

    Any info on this would be extremely appreciated.


  • Bug: 500 Error when viewing files via direct link in GitLab web viewer
    timweddeT timwedde
    GitLab

    @nebulon Can confirm as well, thanks for the quick turnaround!


  • Bug: 500 Error when viewing files via direct link in GitLab web viewer
    timweddeT timwedde
    GitLab

    I've recently been encountering this and figured I would report it here.

    This seems to occur because of how GitLab is packaged for Cloudron as I was unable to reproduce this issue on gitlab.com proper.
    However, I was able to trigger this issue on both Cloudrons I manage as well as on the official Cloudron GitLab instance as well.

    The error manifests when attempting to view a file via the built-in editor in GitLab. Navigating to a file via the interface works, but if you reload the file once it's open or alternatively navigate to its link directly, you will be greeted with a 500 error.

    Example link:
    https://git.cloudron.io/cloudron/gitlab-app/-/blob/master/README.md

    In the logs this manifests as such:

    Completed 500 Internal Server Error in 63ms (ActiveRecord: 3.7ms | Elasticsearch: 0.0ms | Allocations: 12843)
      
    ActionView::Template::Error (Can't find entry point 'monaco' in webpack manifest):
        2: - page_title @blob.path, @ref
        3: - signatures_path = namespace_project_signatures_path(namespace_id: @project.namespace.full_path, project_id: @project.path, id: @last_commit, limit: 1)
        4: - content_for :prefetch_asset_tags do
        5:   - webpack_preload_asset_tag('monaco', prefetch: true)
        6: 
        7: .js-signature-container{ data: { 'signatures-path': signatures_path } }
        8: 
    

    I found some things on the GitLab issue tracker about rebuilding frontend caches/packages but am not entirely sure how to achieve this (or whether it would actually help in this case) so any advice (or a potential fix) would be appreciated.

  • Login

  • Don't have an account? Register

  • Login or register to search.
  • First post
    Last post
0
  • Categories
  • Recent
  • Tags
  • Popular
  • Bookmarks
  • Search