Cloudron makes it easy to run web apps like WordPress, Nextcloud, GitLab on your server. Find out more or install now.


Skip to content
  • Categories
  • Recent
  • Tags
  • Popular
  • Bookmarks
  • Search
Skins
  • Light
  • Brite
  • Cerulean
  • Cosmo
  • Flatly
  • Journal
  • Litera
  • Lumen
  • Lux
  • Materia
  • Minty
  • Morph
  • Pulse
  • Sandstone
  • Simplex
  • Sketchy
  • Spacelab
  • United
  • Yeti
  • Zephyr
  • Dark
  • Cyborg
  • Darkly
  • Quartz
  • Slate
  • Solar
  • Superhero
  • Vapor

  • Default (No Skin)
  • No Skin
Collapse
Brand Logo

Cloudron Forum

Offical apps | Community apps | Demo | Docs | Install
L

LoudLemur

@LoudLemur
Unfollow Follow
About
Posts
2.3k
Topics
512
Shares
0
Groups
0
Followers
5
Following
3

Posts

Recent Best Controversial

  • 🚀 Cognee on Cloudron - Community Package now available
    L LoudLemur
    Community Packages cognee ai agents documents

    @timconsidine said:

    ust out of interest, did you consider EverOS but preferred Cognee, if so for what reason ?

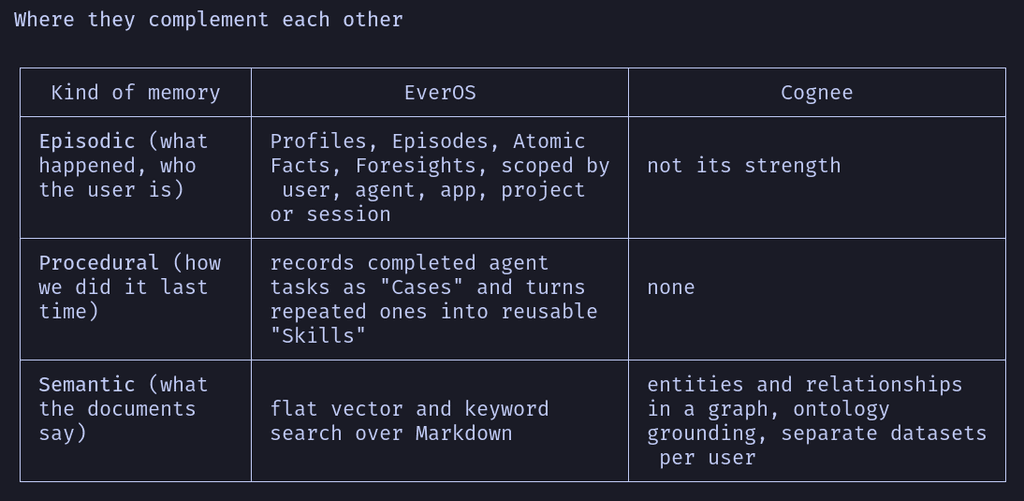
    Hi, Tim! Yes, we held EverOS in mind while we were considering whether to package Cognee and considered their relative strengths and overlap. It was ontology, mainly.

    We read EverOS as a different tool in the same area rather than a substitute. As far as we could tell from its listing, it's agent memory: conversations and agent runs become Markdown memories (profiles, episodes, facts, and Cases that turn into reusable Skills), and you search them with vector and keyword search. What we were after was the other half: point it at a pile of documents, pull out the entities and relationships, and query the resulting knowledge graph. Nothing on either store did that extraction, and that's Cognee's job.

    So it wasn't "Cognee instead of EverOS". If anything they look complementary: EverOS for what the agents and their users have done, Cognee for what the documents say. Since both write plain Markdown or take it over a REST API, a scheduled job could push the Skills and facts EverOS distils into Cognee and build them into the graph. That's an untried idea, not something we've done.

    Screenshot_20261003_111045.png


  • 🚀 Cognee on Cloudron - Community Package now available
    L LoudLemur
    Community Packages cognee ai agents documents

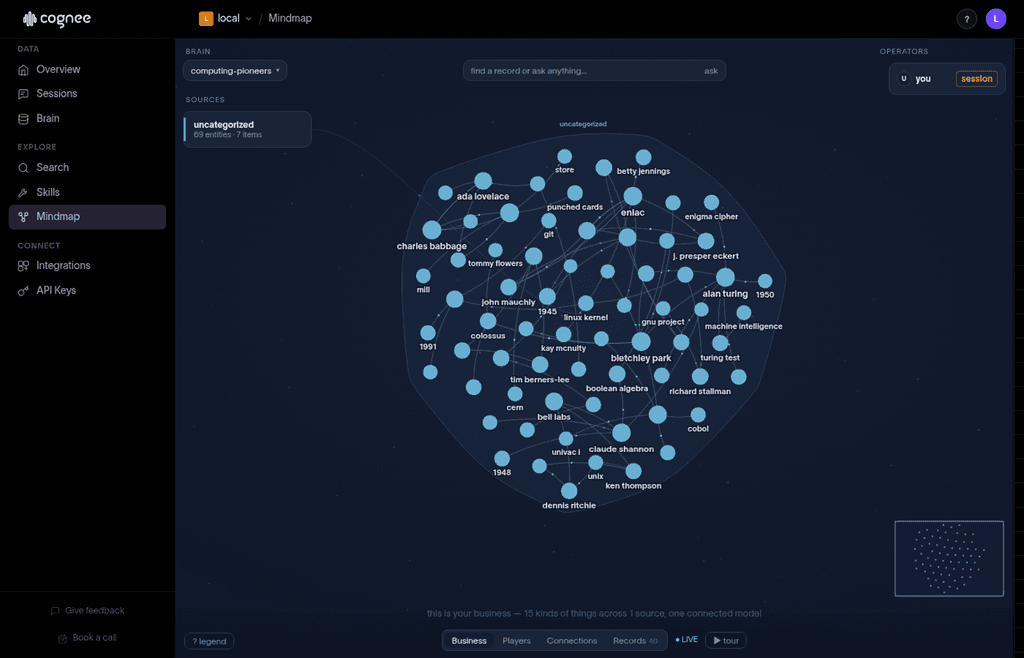
    TL;DR: Cognee turns documents into a knowledge graph plus a vector index that your agents can query. It is now packaged for Cloudron, runs with no API key out of the box, and takes any OpenAI-compatible model when you want answers as well as search. Unofficial and community-maintained.

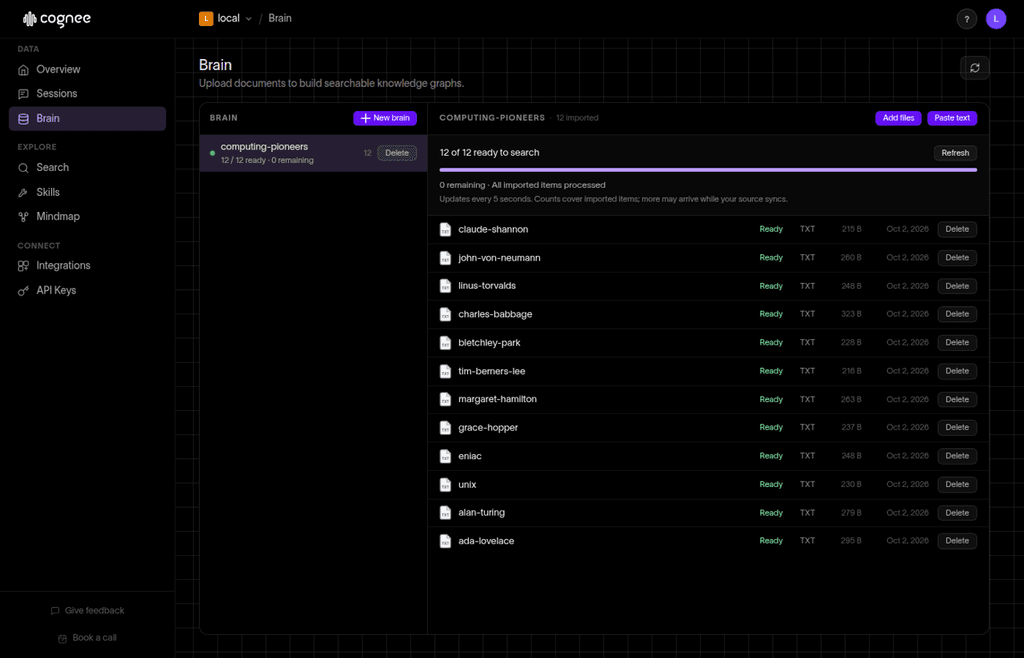
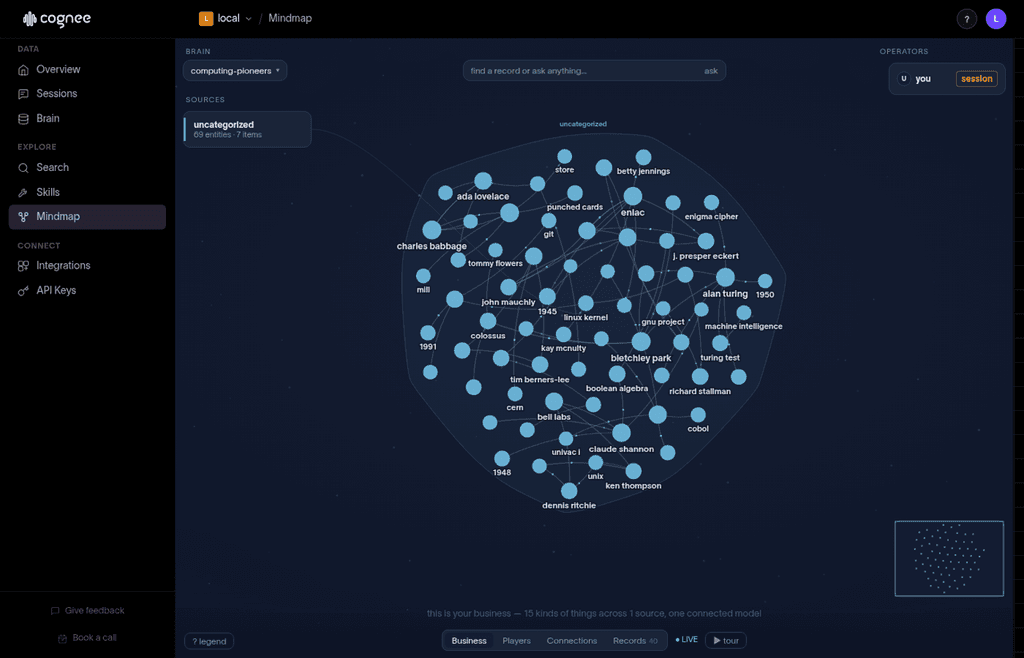
    mindmap-1280.png

    brain-1280.png

    Headline features

    • Add documents in the web interface or over the REST API, build a graph with one call, then search by chunk, by graph, or by asking a question.
    • Works with no API key: a small local model extracts entities and another embeds the text, both downloaded the first time they are needed.
    • Bring your own model when you want richer graphs and answer-style search: any OpenAI-compatible chat endpoint and embedding endpoint, set through the app's environment.
    • Safe defaults: self-registration closed, telemetry off, signing secrets and the administrator password generated once and kept in the data directory.
    • The downloaded models live outside the backups, so a backup stays small. A restored app fetches them again on first use.

    Links

    • Project homepage: https://www.cognee.ai
    • Upstream repo: https://github.com/topoteretes/cognee
    • Cloudron package repo: https://github.com/OrcVole/cognee-cloudron

    This package runs upstream release 1.6.2 with its own web interface (the Brain, Search and Mindmap pages are the useful ones).

    mindmap-1280.png

    How to install

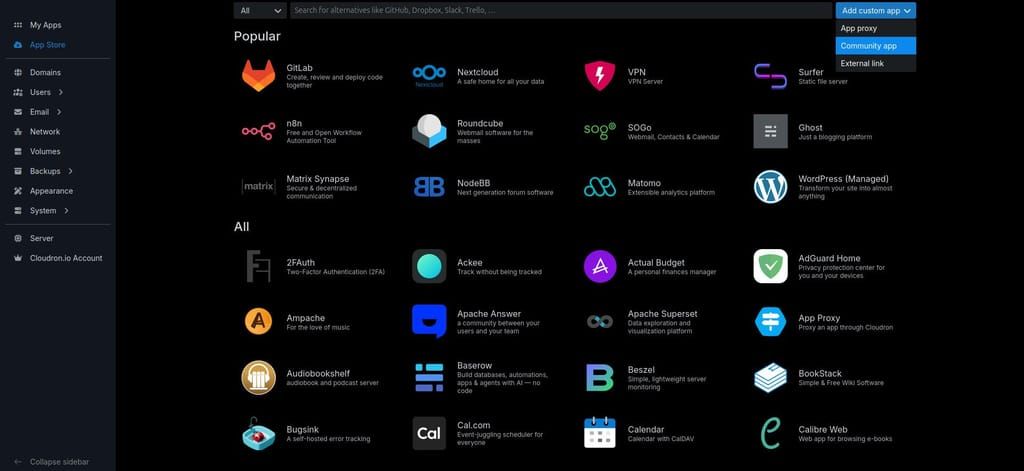
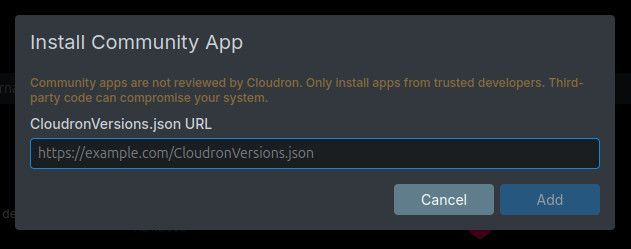
    The easiest way is the dashboard: click the Add custom app dropdown (top right in the App Store), choose Community app, and paste the CloudronVersions.json URL below into the box. Apps installed this way receive automatic updates.

    community-package.jpeg

    cloudronversions.jpeg

    https://raw.githubusercontent.com/OrcVole/cognee-cloudron/main/CloudronVersions.json
    

    Or with the CLI:

    cloudron install \
      --versions-url https://raw.githubusercontent.com/OrcVole/cognee-cloudron/main/CloudronVersions.json \
      --location cognee.example.com
    

    Minimums: Cloudron 10.0.0 or newer. The memory limit defaults to 8 GiB, because the two local models stay in memory once loaded. With a language model and an embedding endpoint configured the app needs far less, and you can lower the limit in the dashboard. Addons: localstorage and postgresql. No extra subdomain.

    First run: sign-in is by email and password, because Cognee has no single sign-on. The post-install checklist asks you to set a real administrator address, and the generated password is in the data directory as described in the post-install note. There is no mail, so no password reset by email.

    For users

    Why try it: agents forget. Cognee keeps what they have read as a graph of entities and relationships plus a vector index, so they can recall facts and how they relate. You get the web interface, an API key page for your agents, and the Cloudron basics: automatic backups, one-click updates and a certificate. Good fit if you want a private memory layer next to your other apps. Probably not if you need single sign-on or mail.

    For packagers: what we learned

    What helped: the platform's PostgreSQL addon covers the relational store, and persistentDirs is exactly right for a model cache you do not want in backups.

    What was tricky: the extraction runtime has to be installed at build time because installing it at runtime fails on a read-only filesystem. The front proxy must pass the original Host header including the port, or the interface's server actions fail behind the platform proxy. With the local models loaded the app needs about 5 GB, and a 4 GiB limit was never killed but swapped heavily, so look at the limit-hit counter and not only at out-of-memory kills.

    Still rough: a cold install from the community store on a fresh subdomain is the thing we would most like confirmed by someone else.

    For the Cloudron team

    Maintenance burden: upstream releases often; the package is thin, with the version pinned in one place. Why it suits the store: agent memory is a gap among the community apps, and Cognee completes a stack with an LLM server and an embedding server. Friction worth knowing: the dashboard does not show a memory limit being hit repeatedly when swap absorbs the overflow, and the CLI has no memory-limit flag for a standing app.

    For Cognee's developers

    Thank you for an Apache-licensed project that runs without a key. A few low-effort asks would help anyone packaging it: an environment variable for the extraction model name, a note that the embedding cache defaults to a temporary directory, and a switch to disable the register route. Package source and pull requests are welcome.

    Unlocks

    Now you can keep a private knowledge graph of your own documents on your own Cloudron, queried by any agent that speaks to a REST API.

    Synergies

    • Cognee + Text Embeddings Inference, or TEI: point Cognee's embeddings at a TEI install, so embeddings are served by a shared service rather than loaded inside the app.
    • Cognee + Langfuse: send Cognee's model calls to a Langfuse project to see every extraction call and its cost.
    • Cognee + vLLM, Ollama, Open WebUI or LibreChat: any of their OpenAI-compatible endpoints can be the language model for extraction and answers.
    • Cognee + Docling: convert PDFs and office files to text with Docling, then add them to a Cognee dataset.

    Feedback, bug reports, and "works on my install" confirmations are all welcome.


  • Hosting provider pricing
    L LoudLemur
    Off-topic

    SSDnodes have been reliable for us and they offer loads of RAM. Perhaps we have been lucky, but we would definitely try them again. Their CPUs are older generation though, so you might need something more modern.


  • Paperclip - Open-Source Orchestration Platform for Teams of AI Agents at Work
    L LoudLemur
    App Wishlist

    @Teiluj said:

    Thanks for considering packaging paperclip.

    We have created a package for Paperclip and have it running but are waiting to hear from upstream before publishing it.


  • AI supported bug diagnosis and reporting on Cloudron
    L LoudLemur
    Feature Requests bugs omarchy automation feature-request

    https://x.com/NetworkChuck/status/2103557052681376169?s=20

    Check out the speaker's bio @dhh (Creating Ruby on Rails was the least of it!)

    The distro he has created is Omarchy.

    The system he proposes where AI kicks in every time a bug crashes, investigates, sends a bug report which is then reviewed by other ai agents might be something we could try on Cloudron.


  • 🚀 Meilisearch on Cloudron: Community Package now available
    L LoudLemur
    Community Packages meilisearch search api cloudron

    @james We have created a feature request for this:

    https://forum.cloudron.io/topic/16011/full-backup-carry-on-past-a-failing-app-then-keep-the-backup-marked-as-partial


  • Full backup: carry on past a failing app, then keep the backup marked as partial
    L LoudLemur
    Feature Requests backups

    Following on from @james's suggestion in https://forum.cloudron.io/post/129999 .

    What happens today

    In fullBackup() (src/backuptask.js, the same in 10.0.4, 10.0.5 and master), each app is backed up in turn inside a loop, and the first failure ends the whole run:

    const [appBackupError, appBackupResult] = await safe(backupAppWithTag(app, ...));
    ...
    if (appBackupError) throw appBackupError;
    

    Mail and the system data are only backed up after the loop, so when one app fails, every app after it in the list, plus mail and the system data, gets no backup from that run. If the failure persists (an app whose backupCommand keeps failing, for example), the same thing happens every night.

    Why it matters

    For a whole-server restore, one app with a flagged, incomplete backup is much better than a server where half the apps, the mail and the system data have no fresh backup, all because of an app that may sit early in the list.

    It also leaves app packagers with two bad choices when a backupCommand cannot produce a complete backup. Exiting non-zero is honest, but it costs every other app on the server its backup. Exiting zero protects the others, but hides the failure from the platform, so packages end up inventing their own notices (our Meilisearch package writes a BACKUP-FAILED.txt and repeats it in the log at every start). We would much rather fail honestly.

    What we are asking for

    1. When an app's backup fails, record the failure and carry on with the remaining apps, then mail and the system data.
    2. Keep the resulting backup, but mark it as partial, and name the app or apps that failed and why.
    3. Report the run as failed, with a notification naming those apps, so nothing passes as fine.
    4. For the failed apps, either leave them out of the partial backup or point to their last good backup, but say which, so that a restore from a partial backup warns before it restores an app from something older or incomplete.
    5. Do not let partial backups count towards retention in a way that prunes the last complete backup. Otherwise a week of partial runs could rotate out the only full one.

    With that in place, packages can exit non-zero whenever their backupCommand genuinely fails, and the platform stays the one place where backup health is reported.

    We are happy to test a build against a package with a deliberately failing backupCommand.


  • Cloudron 10 released
    L LoudLemur
    Announcements

    @girish
    Congratulations on releasing Cloudron 10.

    The part of the announcement post I liked most was the origin story, how you loved RSS/Atom and had a great collection of feeds and that all came asunder when Google Reader was stopped. It is great that you and Johannes started Cloudron then.

    I have always thought RSS/Atom is great tech. If its popularity became more widespread, people would stay off proprietary platforms much more.

    What I want to know is how you managed responding to what you read and browsed, because being able to react is part of the great fun of the internet.

    Also, i have tried weaning myself back onto a life of RSS/Atom a few times but can't seem to make the break from the websites. Do you have any tips on how to do that and especially how to comment without jumping back onto the web-browser again.


  • 🚀 Meilisearch on Cloudron: Community Package now available
    L LoudLemur
    Community Packages meilisearch search api cloudron

    Thank you, @james. You have it right, and I agree with the principle: a backup that is missing something should say so, and a full-server backup that contains a broken app should not pass as fine.

    My concern is narrower than that. In 10.0.4, fullBackup rethrows the first app error inside its loop (if (appBackupError) throw appBackupError; in backuptask.js). So when one app's backupCommand fails, every app after it in the loop, plus mail and the system data, is not backed up at all.

    That makes a whole-server restore worse than an app failing honestly. Instead of one app with a flagged, incomplete backup, it gets a server where half the apps have no fresh backup, all because of an app that may be at the far end of the list.

    So the question was really this: Could fullBackup carry on through the remaining apps, then mark the whole backup as failed and name the app that failed? The run would still fail, as you say it should, but one app would not cost all the others their backup.

    If that is how it behaves, or once it does, we will make the Meilisearch package exit non-zero when its snapshot fails, because that snapshot is what a restore needs. A failed dump would stay a logged warning, since the snapshot alone still restores. Until then, the notice file is our way of not failing silently without taking everyone else's backup down with us.


  • Two small manifest fields for slow-starting and long-running apps (AI servers especially)
    L LoudLemur
    Feature Requests healthcheck timeout

    Thank you, @james. You were right, and more right than we knew: please disregard request 2 as well.

    Before replying, we measured it instead of repeating our notes.

    • The platform does not cut at 60 seconds. The app proxy in nginxconfig.ejs sets proxy_read_timeout 3500, and it has done so since at least 8.3.0.
    • A test confirms it. On 10.0.4 we installed a small app whose endpoint stays completely silent before answering. Through the reverse proxy it answered 200 after 30, 75 and 150 seconds.
    • The 60 seconds we saw came from a client's own timeout. We blamed the proxy because a call to localhost worked, and that was an inference we never tested. It then spread through our notes into this request. Sorry for the noise, twice in one thread.

    Your design point stands, and the IONOS example makes it well: a longer timeout only moves the wall. Where an upstream can stream or report progress, our packages will say so and default to it, because real clients do time out. We are also correcting the documentation in our packages that repeated the wrong cause.


  • 🚀 Meilisearch on Cloudron: Community Package now available
    L LoudLemur
    Community Packages meilisearch search api cloudron

    Thank you, @james, for such a careful review, and for the kind words. We checked all three of your findings against our own evidence, and all three are right.

    What we found

    • Restore did not roll back the search data. Our own gate had measured it: the backup held 260,000 documents and the store still held 1,000,000 after the restore. We scored it as a pass because nothing was lost. The persistent store survives an in-place restore, and without a restoreCommand nothing replaced it.
    • Snapshots only, and the dump fallback was dead code. As you said, a snapshot is not portable between Meilisearch versions. Our upgrade-failure path did fall back to a dump, but nothing ever wrote one.
    • A failed backup was invisible unless you read a log file inside /app/data.

    What we changed, in package 1.2.0 (published)

    • A restoreCommand. After a restore or clone, the live store is moved aside (kept for 30 days) and rebuilt from the backup's snapshot. If a backup has no snapshot, the live store is kept and a warning is logged, rather than replacing it with nothing.
    • Every backup now takes a dump as well as a snapshot, so the version-portable copy exists.
    • A failed backup writes /app/data/BACKUP-FAILED.txt, and the app repeats it in its log at every start until a backup succeeds.

    We gated it on Cloudron 10.0.4. We installed the published 1.1.0 from its feed and updated it to 1.2.0 over 2,000 documents. After a backup we added 500 more, then restored: the count came back to 2,000, with the content fingerprint identical to the backup's. A clone from the same backup matched too.

    One place where we kept our approach, and a question

    The backup command still exits 0 when it fails. In 10.0.4, fullBackup in backuptask.js rethrows the first app error from inside its loop, so one app's failing backupCommand stops the backup of every app after it, plus mail and system data. Exiting 1 on a failed dump would cost the whole server its nightly backup. Could fullBackup record a per-app failure and carry on, or raise a notification? Then packages could fail honestly instead of writing a notice file.

    Your tenant-token tooling, now merged

    Thank you for offering to move everything into one package. Your multi-tenancy tooling was the part ours lacked, and package 1.3.0, now published, carries it: meili-token.sh and your guide, adapted to this package's master-key file and env file. It is opt-in, so existing installs see no change on update: set MEILISEARCH_TENANT_TOKEN_KEY=true in /app/data/env and restart, and the app creates a search-only signing key in /app/data/tenant-token-signing-key.env. Setting it back to false deletes the key and revokes every token it signed. We also took your dumps/latest pointer: a backup now records which dump it completed, and a rebuild imports that one rather than whichever is newest, so a half-written dump can never be used. The changelog and README credit you, and the guide is in docs/TENANT-TOKENS.md. If anything in the port does not match how you meant it to work, please say so and we will fix it.


  • 🚀 Meilisearch on Cloudron: Community Package now available
    L LoudLemur
    Community Packages meilisearch search api cloudron

    @james said:

    Maybe you could look into these findings and we can move everything into your community app.

    Thank you, James. We will get onto this right away and will try and improve it as you suggested.

    It is ironic that search packages found each other like this. I also packaged an application for cloudron and found that somebody else had already created one! We must be soul mates. It is kind of like a dating site where Packagers go to find people with similar interests!


  • Paperclip - Open-Source Orchestration Platform for Teams of AI Agents at Work
    L LoudLemur
    App Wishlist

    Thank you for the request, @Teiluj. We like Paperclip and we are going to package it as a community app.

    Before we do so, here are some concerns which people who might want to use a Paperclip package may like to read, because this app is not like most on the store.

    What concerns us

    • Agents run inside the app. Paperclip starts Claude Code, Codex and similar tools as processes in its own container, and upstream hands them the server's full environment. On Cloudron that includes the database credentials, and the key that encrypts every stored secret is a readable file. An agent that reads a hostile ticket or repository could take over the whole Paperclip instance.
    • Upstream's sandbox cannot run here. It relies on Linux namespaces, which Cloudron app containers do not allow.
    • The internal network is reachable. Any app container can reach the shared database servers and other apps directly, which also bypasses proxyAuth. An unconfined agent would be a foothold inside the server, not just inside Paperclip.
    • Sign-in is email and password only. There is no OIDC yet (it is an open pull request upstream, not a plugin), and the server sends no email at all, so there is no password reset.
    • It moves fast. Releases are roughly weekly, and one recent release carried 49 database migrations.

    One correction to the post above: Paperclip does not use Redis or Qdrant. It needs only PostgreSQL, which the Cloudron addon provides.

    How we intend to handle it

    • Agents run as a separate, unprivileged user, started through a narrow sudo rule with a clean environment. They cannot read the database credentials, the encryption key or the server's memory.
    • A firewall inside the container, matched on that user for both IPv4 and IPv6, blocks the internal network and outbound mail. The internet, DNS and Paperclip's own API stay open.
    • Process and file-size limits apply to the agent user.
    • Telemetry is off by default, and so are Paperclip's own database dumps, because Cloudron already backs up PostgreSQL.

    We have tested this design on a test Cloudron. The agent user was refused on every database and every other app, saw no secrets, and still reached the internet.

    Advantages

    • You can run local agents without handing them the server.
    • It works on stock Cloudron. It needs only the net_admin capability, which Cloudron offers to apps: no Docker socket and no privileged container.
    • The listing will say plainly what an agent can and cannot reach.

    Drawbacks

    • All agents share one user, so one agent can read another's workspace.
    • Agents can still reach the internet, so anything an agent can read, it can send out. For untrusted input, a remote sandbox or an agent in its own app (OpenClaw and Hermes Agent are already in the store) remains the better choice.
    • An agent can still fill the disk.
    • Board users can run any command in the app, so treat them as administrators.
    • There is no SSO and no password reset until upstream adds them.
    • Updates to the application (but perhaps not the package) will be frequent.

  • Two small manifest fields for slow-starting and long-running apps (AI servers especially)
    L LoudLemur
    Feature Requests healthcheck timeout

    @james said:

    A failing health check does not cause the app to restart, there must be something else going on.

    @james You are right, thank you. We rechecked: the same change that added our shim also raised the memory limit, and the container was exiting 137, an OOM kill. The memory was the fix, not the shim. Please disregard request 1.

    Request 2 stands. A slow cold-model call completes via localhost inside the container, but through the reverse proxy it is cut at 60 seconds every time.


  • Looking for testers with an AMD or Intel GPU: does Vulkan compute already work through vaapi?
    L LoudLemur
    Discuss cloudron gpu amd intel

    While the NVIDIA route (topic 15756) waits on the platform, there may be a shortcut for AMD and Intel graphics that needs no platform change at all. We cannot test it, because none of our servers has an AMD or Intel GPU (graphics processing unit). If yours does, ten minutes would settle it.

    The idea: The vaapi manifest capability passes the host's whole /dev/dri into the app container. On AMD and Intel, Vulkan compute goes through the same render node (/dev/dri/renderD128), via Mesa's RADV and ANV drivers. If the app can open that node, then llama.cpp and whisper.cpp, which both have Vulkan backends, could run GPU-accelerated on Cloudron today. That would mean local language models and transcription with no CUDA and no new platform feature.

    No installation needed. If you already run an app that declares vaapi (Jellyfin does), open its Web Terminal and paste:

    ls -l /dev/dri
    stat -c '%n %U:%G gid=%g mode=%a' /dev/dri/renderD*
    id
    id cloudron 2>/dev/null

    Please reply with the output, plus your GPU model (for example from lspci | grep -i vga on the host) and your Cloudron version. What we are looking for: the render node is present, and the user the app runs as can read and write it, either through the group or the mode.

    Stage 2, if stage 1 looks good. We built a small diagnostic app for this. It is on our Forgejo, short enough to read before you run it: https://forgejo.wanderingmonster.dev/WanderingMonster/cloudron-gpu-testing/src/branch/main/vulkan-probe

    1. Install the Cloudron command-line tool if you do not have it: npm install -g cloudron, then cloudron login.
    2. Make an empty folder and fetch the manifest into it: mkdir vulkan-probe && cd vulkan-probe && curl -fsSLO https://forgejo.wanderingmonster.dev/WanderingMonster/cloudron-gpu-testing/raw/branch/main/vulkan-probe/CloudronManifest.json
    3. In that folder, run: cloudron install --image forgejo.wanderingmonster.dev/wanderingmonster/vulkan-probe:0.1.0 --location vulkan-probe. The image pulls without an account.
    4. Wait about a minute, open the app, and reload until the page ends with a VERDICT: line.
    5. Paste the whole page here, with your Cloudron version. It contains no keys, domain or IP address; it does name your CPU, GPU and kernel.
    6. Uninstall it: cloudron uninstall --app vulkan-probe. It stores nothing.

    The README at that link explains each verdict. On our own AMD integrated GPU, outside Cloudron, the app user reached the GPU and llama.cpp ran on Vulkan. What we cannot test is a real Cloudron server with Docker, AppArmor and a 0660 render node, which is where you come in.

    If this works, we will write it up for everyone and suggest the docs describe vaapi as "GPU render node access", not only video decoding. Thank you!


  • Two small manifest fields for slow-starting and long-running apps (AI servers especially)
    L LoudLemur
    Feature Requests healthcheck timeout

    We package several AI servers for the community store (text embeddings, reranking, speech, LLM inference). Two platform limits come up in almost every one, and both look cheap to lift. They sit alongside the gpu capability (topic 15756) and /dev/shm size (topic 15844) you have already agreed to, and are not a bump of either.

    1. A start period for the health check. Several model servers only bind their HTTP port after warming up the model, which takes tens of seconds on a CPU. During that window healthCheckPath gets connection-refused rather than a 503, and the app restart-loops before it is ever ready. A local docker run never shows this, because Docker does not health-check during warm-up, so it only appears on a real box. Our workaround is an nginx shim inside the image that answers /health at once and proxies everything else. It works, but every package has to rediscover it. Suggested shape: an optional healthCheckStartPeriod in seconds, like Docker's own HEALTHCHECK --start-period, during which failures are not counted.

    2. A per-app proxy read timeout. The reverse proxy cuts a request at about 60 seconds, and it cannot be set per app. A cold-model inference call, a long summary or a large synchronous job hits it, while the app's own server (gunicorn at 600 seconds, for example) would have waited. Streaming responses help where the app supports them, but many endpoints do not stream. Suggested shape: an optional proxyReadTimeout in seconds, with today's value as the default and a sensible maximum.

    Both are optional, both default to today's behaviour, and older boxes can ignore them, like other unknown fields.


  • 🚀 OpenBao on Cloudron: Community Package now available
    L LoudLemur
    Community Packages openbao secrets vault auto-unseal security

    Security update: 1.0.3 (OpenBao 2.6.3). Please update. OpenBao published nine advisories on 23 September, fixed in 2.6.3 and 2.7.0.

    This package ships the 2.6.3 patch release, so there are no new features, only the fixes. The most serious is a CRITICAL remote code execution in which a raft snapshot restore replaces the plugin catalog (GHSA-j6wc-jpvg-xfxq). This package uses raft storage, so it applies here, although it needs a highly privileged token to exploit.

    Also fixed are three HIGH issues: an ACL bypass via non-canonical URLs, a cross-namespace policy cache flaw, and unvalidated SANs through PKI ACME. There are also an open redirect in the OIDC provider UI and four low-severity issues.

    The update also moves the package to Cloudron base 5.1.0. Before publishing, it was tested as an update over real secrets, including a restore into an empty store and an OIDC sign-in, and it's already running in production.

    Some scanners will still list a few old OpenBao CVEs against the bao binary. Those are false positives: the release binary reports its Go module version as v0.0.0-…. Upstream is fixing that in 2.7 (openbao/openbao#3184).

    We love Bao and will do our best to keep this package well maintained.


  • Langfuse on Cloudron - Community Package
    L LoudLemur
    Community Packages langfuse ai observability tracing llm

    Update: 0.10.0 (Langfuse 4.43.0) is out. It moves to Cloudron
    base 5.1.0 and applies two Postgres migrations and one small Click
    House migration automatically on first start.

    Something to know: a vulnerability scanner will report four CRITICAL findings, all in the bundled MinIO and its mc client. No fixed MinIO build exists yet, and the affected parts (AMQP notifications, a gRPC server) aren't used by this packag
    e. Replacing MinIO is next on the list.

    We expect to move to a slower cadence for Langfuse updates or security-only, because upstream releases almost daily.


  • 🚀 Crawl4AI: community package now available
    L LoudLemur
    Community Packages crawl4ai ai crawler

    Big thanks to the brilliant @timconsidine for his interest and vigilance and for immediately notifying we were initially on an older base image of cloudron.

    This crawl4ai is now on Cloudron 5.1 and we will be moving the rest of our fleet to the new base when they need updates, too.


  • 🚀 Crawl4AI: community package now available
    L LoudLemur
    Community Packages crawl4ai ai crawler

    TL;DR: Crawl4AI fetches web pages with a real headless browser and returns clean Markdown, HTML, a screenshot or a PDF, for feeding into language models or automation workflows. Now packaged for Cloudron and ready to install. Built and tested on Cloudron 9.x; unofficial and community-maintained.
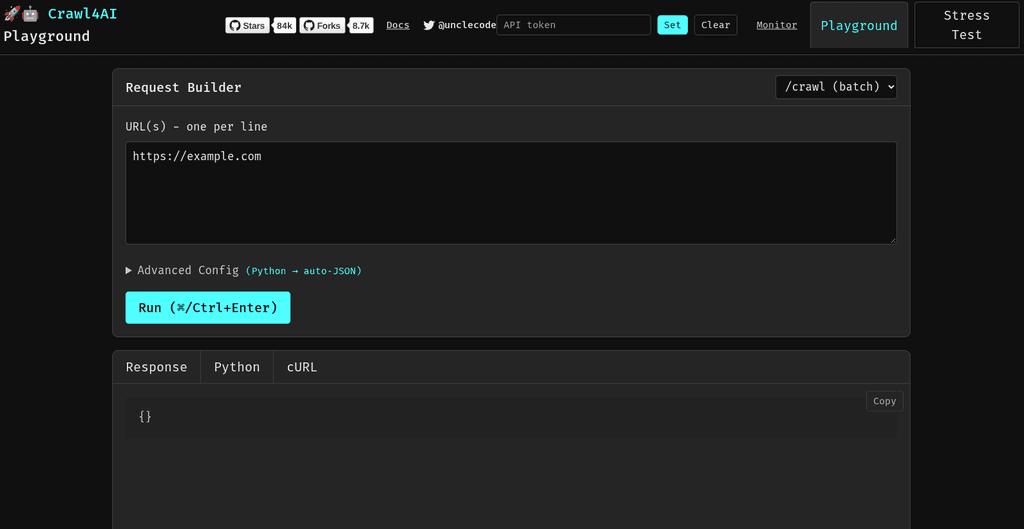
    Screenshot_20260923_162417.png

    ✨ Headline features

    • Real Chromium rendering, so JavaScript-heavy pages work, not just static HTML.
    • Four output shapes from the same request: Markdown, cleaned HTML, a screenshot, or a PDF.
    • A REST API and an MCP endpoint, so an AI agent tool can call it directly.
    • A Redis-backed job queue for larger crawl batches, alongside the synchronous endpoints.
    • Every request requires an API token, generated automatically on first start; there is no way to reach it without one.

    Links

    • 🏠 Project homepage: https://github.com/unclecode/crawl4ai
    • 📦 Upstream repo: https://github.com/unclecode/crawl4ai
    • 🧱 Cloudron package repo: https://github.com/OrcVole/crawl4ai-cloudron

    There is a small built-in playground UI once installed (shown above), for trying requests by hand before wiring them into a script.

    📥 How to install

    community-package.jpeg

    cloudronversions.jpeg

    Click the Add custom app dropdown (top right in the App Store) and choose Community app, then paste this URL into the box that pops up. Apps installed this way receive automatic updates.

    https://raw.githubusercontent.com/OrcVole/crawl4ai-cloudron/main/CloudronVersions.json
    

    Or from the CLI:

    cloudron install \
      --versions-url https://raw.githubusercontent.com/OrcVole/crawl4ai-cloudron/main/CloudronVersions.json \
      --location crawl4ai.example.com
    

    Minimums: 2 GiB RAM, localstorage addon only; no other subdomain claimed.

    First run: there is no login page. Read the auto-generated API token from /app/data/.secrets/api-token via the Cloudron file manager or the app's web terminal, then send it as a Bearer token on every request.

    👤 For users

    Why try it: you want clean Markdown or a screenshot from a page, including pages that need JavaScript to render, without running a scraping stack yourself. What you get: a REST API for one-off requests, a job queue for batches, and an MCP endpoint so an AI agent tool can crawl on your behalf. Cloudron wins: no separate server to provision, managed updates, everything under /app/data. Good fit if you already automate against APIs or run agent tooling; probably not if you only need to read one page occasionally, where a browser extension is simpler.

    🧰 For packagers: what we learned

    What helped: upstream ships a single self-contained image with Python, the app and the Playwright browser cache already in place, so the build is a straight copy onto cloudron/base plus playwright install-deps, the same shape used for our other Chromium-based packages.

    What was tricky: no Chromium sandbox is available inside a Cloudron container (no CAP_SYS_ADMIN, restricted user namespaces, 64 MiB /dev/shm); we asked about this here first (see the earlier thread) and ship --no-sandbox with the mandatory API token and a default refusal of internal-network URLs as compensating controls, which is the same situation every headless-browser app faces on this platform. Redis needed relocating to a writable directory outside /var/lib/redis. The upstream memory_threshold_percent setting does not protect the HTTP endpoints, only the internal dispatcher, so we size memoryLimit and the default concurrency by measurement instead.

    Still rough: the default concurrency (10 pages) and the 2 GiB default memory limit have thin headroom under sustained load in our own testing; we are tightening one or the other before the next release.

    🛠️ For the Cloudron team

    Maintenance burden: upstream ships frequently, including at least one security release during this package's first day, so the package needs active per-release pin verification rather than an occasional glance. Why it suits the App Store: clear demand for self-hosted AI tooling, a clean Apache-2.0 upstream, and it completes an AI stack alongside existing store packages for vector databases and inference. Friction worth knowing: cloudron versions init suggests adding packageUrl to the manifest, which then conflicts with minBoxVersion below 10.0.0; removing the field again fixes it.

    💻 For Crawl4AI's developers

    A couple of low-effort things that would help future packaging: a documented minimum glibc/Ubuntu base for the bundled Playwright browsers, and a config knob (or documented behaviour) for memory_threshold_percent to also gate the synchronous HTTP endpoints, not only the internal dispatcher. Package source and PRs welcome: https://github.com/OrcVole/crawl4ai-cloudron.

    🔓 Unlocks

    Now you can run your own crawling and extraction API without a third-party scraping service, and point any MCP-capable AI agent at it for real web access with no separate stack to run.

    🔗 Synergies

    Windmill + Crawl4AI: a Windmill script can call Crawl4AI's REST API as a workflow step, turning a scheduled crawl, a content pipeline, or a page-change check into a few lines of Python against a URL you already trust.

    A self-hosted or local AI setup + Crawl4AI's MCP endpoint: point any MCP-capable agent at /mcp/sse with the API token and it gains real web-crawling as a tool call, no separate crawling stack to run alongside the model.

    A self-hosted knowledge base or note-taking app + Crawl4AI: feed crawled pages in as plain Markdown files, using whichever folder-watching or import mechanism the target app already supports.

    Feedback, bug reports, and "works on my install" confirmations welcome.
  • Login

  • Don't have an account? Register

  • Login or register to search.
  • First post
    Last post
0
  • Categories
  • Recent
  • Tags
  • Popular
  • Bookmarks
  • Search