Cloudron makes it easy to run web apps like WordPress, Nextcloud, GitLab on your server. Find out more or install now.


Skip to content
  • Moved my backup destination

    Solved Support nfs backups
    5
    0 Votes
    5 Posts
    179 Views
    A
    RIght, had to add no_root_squash to the NFS server. remounted & All seems to work again now. Thanks!
  • 1 Votes
    2 Posts
    86 Views
    girishG
    Good catch. Was easy to create a test and fix.
  • 3 Votes
    2 Posts
    105 Views
    nebulonN
    Thanks, this was an oversight and indeed the task got never refreshed. This is fixed then with https://git.cloudron.io/platform/box/-/commit/6178538a4c4b712b426a8b11eeb6ae8ac5fe9f10
  • 4 Votes
    2 Posts
    130 Views
    girishG
    Interesting report. Another quirk of community packages. I wrote the whole backup logic with the assumption that backup fail was something we should fix. If the did fail, either it was some platform error or some external backup service error
  • Backups not working after Ubuntu 26.04 upgrade

    Solved Support backups sudo
    3
    2 Votes
    3 Posts
    173 Views
    sponchS
    omg.thanks - I really thought I did that... working now
  • 1 Votes
    14 Posts
    772 Views
    dsp76D
    Hi @james - I also received a response today. Hope its the same group of people you talk to I let the AI compare the responses: Key differences between response I received and from your summary: Root cause: GC overload vs. synchronous unlinking of old object data. 504: Both say the proxy times out after 600s while backend processing continues. HEAD vs. GET: Response I received assumes processing may still be ongoing and no data loss; from your summary says the affected data is unrecoverable. CopyObject / MPU: Covered as under investigation in response I received; not addressed in your summary. Fix: General GC optimization vs. explicitly decoupling GC from CompleteMultipartUpload. Anyway - looks like we helped uncovering the root cause
  • “Add Backup Site" button is not showing on 9.0

    Solved Support backups
    10
    2 Votes
    10 Posts
    727 Views
    K
    @james said: I am not quite sure what "hidden" post you are referring to, sorry a little confused here. New user so my posts are/were hidden until "approved", it wasn't showing yet, thus "hidden".
  • issue with backups on Scaleway

    Solved Support scaleway backups
    9
    1 Votes
    9 Posts
    691 Views
    jeauJ
    I spent several days trying to understand why backups kept failing on my Cloudron instance. After investigating the issue with Claude’s help, I identified and fixed two infrastructure issues on my own (detailed below for context), but Claude also highlighted a weakness on the Cloudron side: the lack of retries for transient network/DNS errors during S3 backup operations. I’m sharing this report written by Claude here for review. Title: Backup fails entirely on a single transient DNS/network error during S3 copy/list operations — no retry Version: Cloudron 9.2.0 (Ubuntu 22.04.5 LTS Linux 5.15.0-186-generic) Context : self-hosted server, backups to Scaleway Object Storage (S3-compatible), both tar and rsync backup formats affected Summary Over the past week I've had repeated backup failures, all sharing the same final symptom: Error: getaddrinfo EAI_AGAIN cloudron-rsync.s3.fr-par.scw.cloud This occurred at different stages of the backup pipeline across different incidents: during initial tar packing/upload, during copyInternal (S3-to-S3 copy for snapshot rotation), during checkPreconditions (mount point check), and during listDir (listing objects for rsync-based copy). The common thread in every case: a single DNS resolution hiccup during a long-running backup (which can involve tens of thousands of individual S3 operations) causes the entire backup task to crash and be marked as failed, with no retry attempted at the DNS/network level or at the individual-operation level. Root causes I found and fixed on my own infrastructure (not Cloudron bugs, but worth noting for context) A local mail service (Haraka, bundled with Cloudron) was stuck in an infinite retry loop performing reverse DNS (PTR) lookups on what turned out to be an IP in the reserved 240.0.0.0/4 range — never a real client IP, likely a bug in Haraka's own DNS-resolution/rDNS-check code generating a bad address internally. This flooded systemd-resolved with several lookups per second, 24/7, unrelated to backup timing. One of my two DHCP-provided DNS resolvers silently failed to respond at all over DNS-over-TCP (confirmed with dig +tcp @<ip>, consistent timeout), while working fine over UDP. When systemd-resolved fell back to TCP (e.g. due to the Haraka-induced UDP noise, or any other reason), it would sometimes pick this broken resolver and hang. Both issues are now fixed (mail service restart + config fix for #1, resolver removed from netplan config for #2), and backups now get much further before any failure — but a single transient DNS hiccup can still occasionally happen (as it can on any network), and it still takes down the whole backup task when it does. What would help Wrap listDir / copyDir / copyInternal (and any other network-dependent step in the backup pipeline) with a retry mechanism (e.g. 3 attempts with exponential backoff) for transient DNS/network errors like EAI_AGAIN, ETIMEDOUT, ECONNRESET. A single flaky lookup during a backup touching 80k+ files should not fail a multi-hour backup task that has otherwise fully succeeded. If a retry budget is exhausted, consider resuming/retrying at the file level rather than aborting the entire task — some backups got quite far (tens of thousands of files copied) before the single failure. More generally: the current behavior converts what should be a transient, self-healing network condition into a hard failure with reason: 'External Error' / 'Internal Error', requiring full backup task re-runs from scratch.
  • 1 Votes
    3 Posts
    335 Views
    girishG
    I have fixed the backupCommand to share the networking namespace with the app - https://git.cloudron.io/platform/box/-/commit/90a8ba1a4915dfbbb30f1073c4f75cd99635ae3d . This is consistent with how the scheduler/cron commands also run. Thanks for reporting!
  • Application unexpectedly missing in Backup

    Discuss backups scheduler
    6
    1 Votes
    6 Posts
    851 Views
    nottheendN
    Update: All apps in error state after Cloudron restore After restoring Cloudron, all my apps ended up in an error state. I've been digging into the logs and wanted to share what I found in case it's relevant to my setup or helps others. The key error from the app task log: Error: ENOENT: no such file or directory, scandir '/mnt/managedbackups/<uuid>/2026-06-10-000001-121/app_<myapp>.<mydomain>_v3.12.2' So during the restore, Cloudron tries to download the app backup from /mnt/managedbackups/..., but that path doesn't exist. This then causes the task to crash with an AssertionError rather than a clean BoxError, which is probably also worth flagging as a minor bug. I suspect this is related to my specific setup: I have an external backup location that is no longer mounted (as described earlier in this thread). Cloudron appears to be pointing the restore at that unmounted path. Resolution that worked for me: Explicitly restoring each app from its most recent backup (rather than letting the automatic restore run) resolved the error state. Ideally, this should be the default behaviour during a Cloudron restore anyway, restoring from the most recent available backup, so this might be worth looking into. Happy to provide more details if useful.
  • backup has started failing

    Solved Support backups
    4
    2 Votes
    4 Posts
    501 Views
    A
    Not sure exactly the cause, however the app being backed up was peertube, and a update was scheduled and failed around the same time. The fix was deleting the corrupt file in the snapshot folder on my truenas from shell. Then re-running the backup
  • BoxError: Another backup task is in progress: Update task is active

    Solved Support backups
    3
    1 Votes
    3 Posts
    411 Views
    J
    Please re-open the topic if you hit the problem in the latest releases.
  • 1 Votes
    3 Posts
    416 Views
    T
    @nebulon Thanks for this - I can confirm that this is an issue with the S3 endpoint and a faulty server app release not accepting upload and throwing HTTP/1.0 400 errors. If I may: The error message about MD5/checksum from Cloudron throw me off for a bit, not directly pointing at a lack of communication with the remote server. Reverting to an earlier release on the S3 endpoint fixed the issue.
  • Google Drive and OneDrive as Backup Destinations

    Feature Requests backups
    4
    2 Votes
    4 Posts
    964 Views
    I
    @robi Yes, I've tested the rclone before that's why I suggest this feature on Cloudron. I don't know the technical requirement on that, maybe what James said it's more a cloud file storage not for the server backup. Thank you Robi and James
  • 0 Votes
    22 Posts
    2k Views
    jdaviescoatesJ
    jdaviescoates said: Yep, the most recent rsync back-up into the new folder (rather than the same folder as the rsync backups were going into before the server migration) worked fine too and now I have rsync backups that pass the integrity check - finally! So it seems clear the issue was some file changes that happening during the full Cloudron server migration got rsync confused. Think I may have spoken too soon. Every rsync back since the one that passed the integrity check has failed it again [image: Screenshot from 2026-10-04 13-30-28.png] It's always the Jellyfin app that fails. Plus once also the Mail server again.
  • Backup crashed

    Solved Support backups
    5
    1 Votes
    5 Posts
    784 Views
    jdaviescoatesJ
    @subven said: Replace your BIOS battery, go into BIOS and set current time, reboot and you should be fine. This is a dedicated server at Hetzner, not a home server. But the backup ran fine before and since, so I think perhaps I'll just not worry about it for now. The bigger completely unrelated issue would appear to be that when I do an integrity check on my rsync backups to Hetzner Storage Box (as opposed to this tarball to Scaleway buckets backup), they fail... I think I'll start a new thread about that.
  • Backups redundant?

    Discuss backups
    8
    3 Votes
    8 Posts
    2k Views
    robiR
    @girish said in Backups redundant?: @robi said in Backups redundant?: Made me ask to what would one restore this if not Cloudron (It's kind of special ! )? There is no standardized format for these backups, would have been great if there was one. One of my previous startups did have such a thing even though the focus was on app migration from any to any.
  • Secondary Backup to Google Drive

    Solved Support backups google drive
    4
    1 Votes
    4 Posts
    782 Views
    robiR
    @joseph yea, one would need to setup rclone to use Google Drive. Hence the old thread about it.
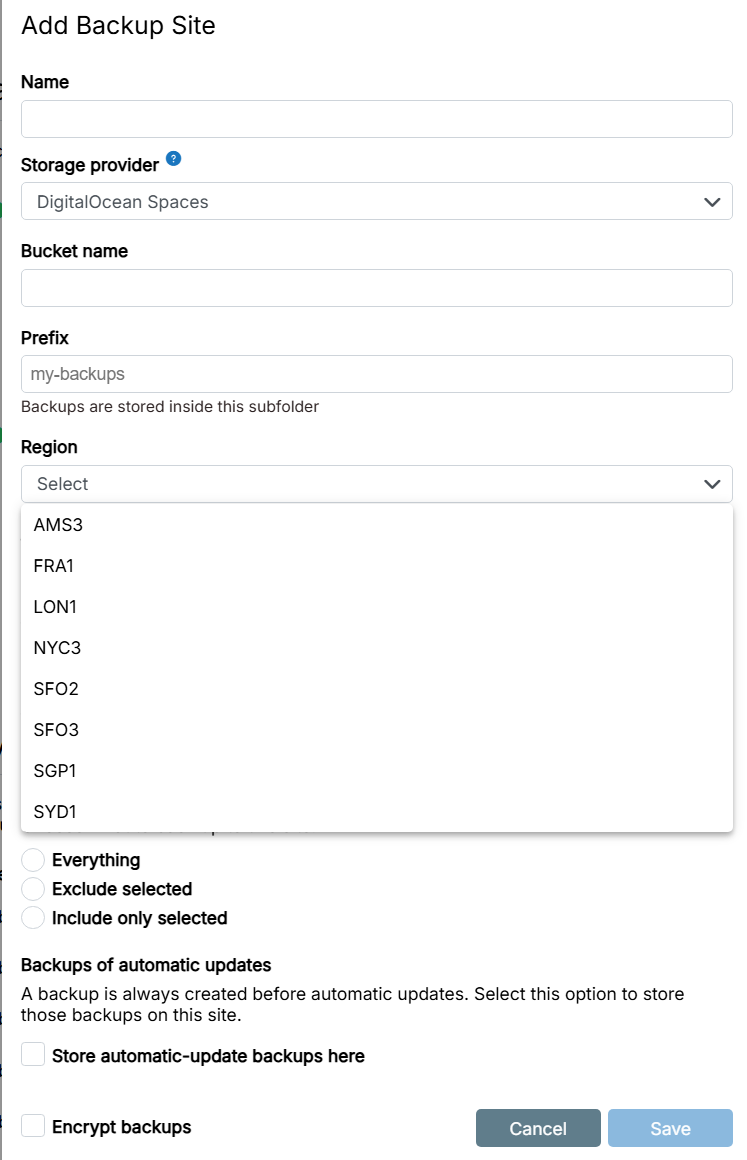
  • Backup Region (DigitalOcean Spaces) not available

    Solved Support digitalocean backups
    2
    1
    1 Votes
    2 Posts
    547 Views
    girishG
    Thanks, fixed - https://git.cloudron.io/platform/box/-/commit/51e02da277d972d1d8b514dc15256f88e2fbe201
  • Cloudron 9.0.15 - App Archive empty in backup

    Solved Support backups archive
    3
    1 Votes
    3 Posts
    665 Views
    jamesJ
    Hello @sebastienserre App Archives are not the same as backups. App Archives is when you go to an app, to the uninstallation section and archive the app. This uninstalls the app but keeps the latest backup as an archive so it can be restored. This archive is stored and kept outside the backup retention policy. See https://docs.cloudron.io/apps#archive [image: 3ca46733-ecad-4ae3-8980-65d96397645c-image.png] [image: f592674b-3485-4155-b11d-048fd845ac60-image.png] Your system backups are viewable under Backups> Sites.