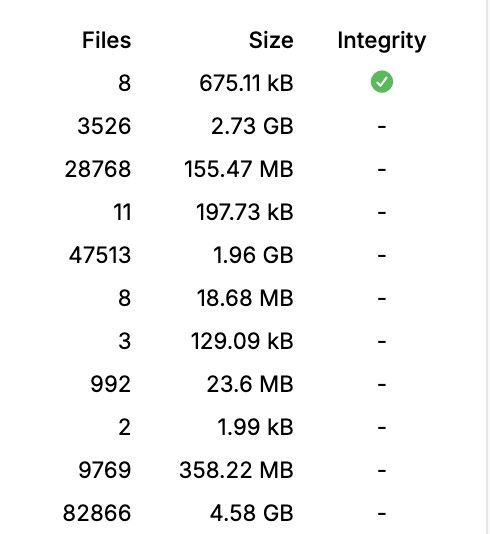
I did, its only 6 days, but the cache already hits 40GB unnecessary backup space.
 D
Dirk Spannaus
@dsp76
Posts
-
Exclude certain paths from backup -
Exclude certain paths from backup -
Exclude certain paths from backup -
Large app backup (~70GB) fails at rotate-copy step with `NoSuchKey` — IONOS S3 read-after-write consistency, but Cloudron has no retryHi @james - I also received a response today. Hope its the same group of people you talk to

I let the AI compare the responses:
Key differences between response I received and from your summary:
- Root cause: GC overload vs. synchronous unlinking of old object data.
- 504: Both say the proxy times out after 600s while backend processing continues.
- HEAD vs. GET: Response I received assumes processing may still be ongoing and no data loss; from your summary says the affected data is unrecoverable.
- CopyObject / MPU: Covered as under investigation in response I received; not addressed in your summary.
- Fix: General GC optimization vs. explicitly decoupling GC from
CompleteMultipartUpload.
Anyway - looks like we helped uncovering the root cause

-
Large app backup (~70GB) fails at rotate-copy step with `NoSuchKey` — IONOS S3 read-after-write consistency, but Cloudron has no retry -
Large app backup (~70GB) fails at rotate-copy step with `NoSuchKey` — IONOS S3 read-after-write consistency, but Cloudron has no retry@james IONOS Support analyzed the situation and comes back with this:
Hello,
Thank you for your patience. Our Platform Engineering team has reviewed and analyzed the log files you provided. Based on this analysis, we can provide the following feedback:
- Propagation delay: There is no artificial delay introduced by our platform. Objects become visible across different operations almost immediately, although not strictly in real time.
- Object consistency: Once a
CompleteMultipartUploadoperation returns the HTTP status code200 OK, subsequentHeadObjectrequests should succeed immediately. Shortly thereafter, all other operations should also become available.
Based on our log analysis, all multipart uploads were completed successfully. However, we observed subsequent
UploadPartCopyrequests referring to anUploadIdthat no longer exists, as theUploadIdbecomes invalid once an upload has been finalized.Could you please clarify where these
UploadPartCopyrequests originate from within your application or client workflow? It appears that after completion of the original upload, an automated post-processing script or background process on your side is being executed, such as aCopyObjectoperation.
Could you please check now on cloudron side? Thanks a lot!
-
Login with TOTP vs Passkey -
Login with TOTP vs PasskeyI saw there are repeatedly passkey issues, which could not be recreated. I also stumbled upon this recently together with a client. Seems like when you setup userid / password with TOTP and add passkey later, login procedure gets confused:
- logged in with userid / password, jumped to TOTP entry mask,
- passkey popup also appears, cancelled by user interaction
- login doesn't proceed successfully
- also when using at the moment the popup appears, login fails.
Choosing "login with a passkey" works fine, but the "old way" to login with userid / pw and TOTP is broken once the passkey is set.
When disabling TOTP for the user, the login trouble is gone. But now its the only way into the account.
Shouldn't both work in parallel? Passkey AND UserID + PW + TOTP?
-
Excalidraw Serverside storing?I only found third party providers that add their own layer to excalidraw, as the open source community edition probably doesn't have it. I didn't yet investigate if that layer is open sourced too. Will let you know what I find.
-
Large app backup (~70GB) fails at rotate-copy step with `NoSuchKey` — IONOS S3 read-after-write consistency, but Cloudron has no retryHi @james I think it means that - once Cloudron receives an error like NoSuchKey oder 404 not found when polling the object directly after upload - it still retries a number of times with exponentially growing delays added with some random delays ("Jitter"). So the error might only be temporal.
-
Excalidraw Serverside storing?Hi @timconsidine
thanks a lot for providing Excalidraw as a community package. Do you have any plans to add a way to store draws on the server?Thanks!
-
Large app backup (~70GB) fails at rotate-copy step with `NoSuchKey` — IONOS S3 read-after-write consistency, but Cloudron has no retryIONOS responded this:
"We are actively investigating the reported behavior. To support our Cloud Engineering team in conducting deeper log analysis within the storage cluster, we kindly request that you provide the following details:
- Target bucket name & IONOS S3 endpoint used during testing
- Request IDs (x-amz-request-id and x-amz-id-2 from the HTTP response headers) for both the CompleteMultipartUpload and the failed UploadPartCopy call
- Timestamps and timezone of the affected runs (or new, millisecond-precision logs if the error can be reproduced again)
While our Engineering team investigates the merging and propagation behavior for large multipart objects in the backend, we recommend testing one of the following client-side workarounds:
-
HeadObject polling with exponential backoff: Before executing UploadPartCopy on newly merged objects larger than 50 GB, insert a short polling loop using HeadObject (with retries on NoSuchKey / 404 Not Found), combined with exponential backoff and jitter. This ensures object metadata is globally visible across all gateway nodes before dependent copy operations are performed.
-
Insert a fixed delay: If implementing a polling mechanism in your Cloudron workflow is not straightforward, inserting a static delay of 1–2 seconds between CompleteMultipartUpload and subsequent copy actions can effectively prevent this race condition issue.
Please let us know whether applying one of these workarounds resolves the issue in your backup runs, and feel free to send us the requested logs once they are available."
I'm not sure if I can get the x-amz-request-id and x-amz-id-2 headers for them.
What do you think about their suggestions? -
20GB is seemingly not enough space to upgrade from 9.2 to 10 :( -
Large app backup (~70GB) fails at rotate-copy step with `NoSuchKey` — IONOS S3 read-after-write consistency, but Cloudron has no retryCloudron version: 10.0.4
Backup storage: IONOS S3-compatible Object StorageSymptom:
The backup upload itself completes successfully, but the immediately following server-side rotate-copy (UploadPartCopy) fails withNoSuchKey, causing the whole backup task to fail withOld backup not found: snapshot/app_<id>.tar.gz.enc. Reproduced on two consecutive daily runs, always on our largest app (~70GB snapshot); other apps (4–70GB) in the same runs succeed.Timeline (Task 11372, millisecond precision):
04:32:30.199  upload stats logged: 72,608,517,172 bytes transferred
04:32:30.285  backupupload: upload completed. error: null   (CompleteMultipartUpload -> 200 OK)
04:32:30.466  Copying (multipart) snapshot/app_c08ad55d-...tar.gz.enc   (rotate-copy starts, 181ms later)
04:32:30.534  Copying part 1 - ... bytes=0-1073741823
04:32:30.535  Copying part 2 - ... bytes=1073741824-2147483647
04:32:30.535  Copying part 3 - ... bytes=2147483648-3221225471
04:32:30.680  Aborting multipart copy   (145ms after part requests)
04:32:30.748  storage/s3: copy error: NoSuchKey: UnknownError
04:32:30.748  copy to .../app_registry.20zen.de_v1.13.0.tar.gz.enc errored. error: Old backup not found
Analysis:
CompleteMultipartUploadreturns success at .285, but the immediately followingUploadPartCopyon the exact same key returnsNoSuchKey~150ms later. This looks like a read-after-write consistency delay on the IONOS backend for very large multipart objects — AWS S3 itself has guaranteed strict read-after-write consistency (including for multipart uploads) since Dec 2020, so this is non-standard behavior on the storage backend side.That said, Cloudron's rotate-copy step (
s3.js: copyInternal) has no resilience for this: no retry, no backoff, no existence check before issuing the copy. A single transient 404 immediately fails the whole backup task, even though a short retry would very likely succeed.Request: Could a short retry/backoff (or a
HeadObjectcheck before copying) be added around the rotate-copy step for large/multipart-uploaded objects, to tolerate brief backend propagation delays on non-AWS S3-compatible providers?(I will also open a ticket at IONOS, but this little improvement would make Cloudron Backups more stable for similar situations with other providers too.)
Relevant stack:
BoxError: Old backup not found: snapshot/app_c08ad55d-….tar.gz.enc at throwError (file:///home/yellowtent/box/src/storage/s3.js:568:49) at copyInternal (file:///home/yellowtent/box/src/storage/s3.js:636:16) at process.processTicksAndRejections (node:internal/process/task_queues:104:5) at async Object.copy (file:///home/yellowtent/box/src/storage/s3.js:670:12) at async Object.copy (file:///home/yellowtent/box/src/backupformat/tgz.js:294:5) -
Backup Integrity check runs into oom -
Backup Integrity check runs into oom -
Broken Update n8n to 2.36.8 -
Broken Update n8n to 2.36.8 -
Broken Update n8n to 4.40.0 - n8n app stuck in restart loop — npm EACCES on /home/cloudron/.npm despite chown in start scriptAfter a failed backup/restart cycle, my n8n app (Cloudron package io.n8n.cloudronapp, v4.40.0) got stuck in a permanent restart loop and won't come back up.
Symptoms:
Healthcheck fails repeatedly: Healthcheck error: Error: connect ECONNREFUSED <app-ip>:5678 (previously EHOSTUNREACH)
On every start attempt, npm fails while installing extra node modules:
npm error code EACCES
npm error syscall mkdir
npm error path /home/cloudron/.npm/_cacache/tmp
npm error errno EACCES
npm error Your cache folder contains root-owned files...
npm error sudo chown -R 1000:1000 "/home/cloudron/.npm"
This happens even on a freshly recreated container (Cloudron deleted and recreated the container as part of a repair/debug task), so it's not a leftover from the old container's filesystem — it recurs immediately on the new one too.
The package's own start.sh already runs chown -R cloudron:cloudron /app/data /run/n8n /run/.npm /run/.cache /run/*.ssh before the npm install step for PKG_EXTRA_NODE_MODULES (a handful of custom node packages), yet the EACCES persists.
The app also briefly entered a Cloudron "Repair mode... sleeping" state during one restart attempt, which I've since disabled.What I've checked:
/run/cloudron.npm (symlink target of /home/cloudron/.npm) is present and empty, owned by cloudron:cloudron (uid 1000).
No supervisorctl socket present (/var/run/supervisor.sock doesn't exist) — image apparently doesn't run supervisord for shell access, only via the packaged start.sh → exec supervisord.
/run is mounted as ext4, not tmpfs, so it's not a "wiped on restart" issue.Question:
Is /run/cloudron.npm (or its _cacache subfolder specifically) expected to sometimes get root-owned entries from an npm install step that runs as root before the gosu cloudron:cloudron npm install line, and if so, is there a known race/ordering bug in the n8n package's start.sh between the chown and the actual npm install for PKG_EXTRA_NODE_MODULES?Workaround used: Restoring from an earlier backup instead of continuing to debug live, since the app was fully down.
Environment:
Cloudron app: n8n (io.n8n.cloudronapp@4.40.0)
Cloudron CLI used for restart/logs -
Robots.txt Feature... shouldn't it warn or show that there is already a robots.txt with some content?